 Ashish Sharma
Introduction: Why Modern Systems Depend on Caching
No money? No problem! Help us pay the cloud hosting bills without opening your wallet—just give
this ad link a click!😉💸
Modern web platforms do not achieve lightning-fast response times by accident. Behind every instant search suggestion, frictionless social media feed, and responsive checkout page lies a carefully planned caching strategy.
When your application repeatedly performs the same expensive computations, database queries, or third-party API calls, response times crawl. At scale, those accumulated milliseconds quickly alienate users and drain compute budgets.
A cache acts as an ultra-fast shortcut. By storing frequently accessed data directly in volatile memory (RAM) instead of querying slower disks or external services, your system returns results in microseconds.
Relational databases represent the most expensive and hardest-to-scale components in any architecture. Serving reads from memory delays costly vertical scaling and preserves disk I/O bandwidth.
Beyond lowering latency, caching shields your primary databases. Diverting read traffic to an in-memory cache preserves database capacity, boosts system throughput, and delays costly infrastructure upgrades. For example, a web service struggling at 10,000 requests per second can scale to several times that volume simply by maintaining high cache hit ratios.
The Multi-Layered Caching Architecture
High-throughput applications rarely rely on a single cache. Instead, architects implement multiple caching tiers that act as protective barriers. Each layer intercepts incoming traffic before requests penetrate deeper into downstream infrastructure.
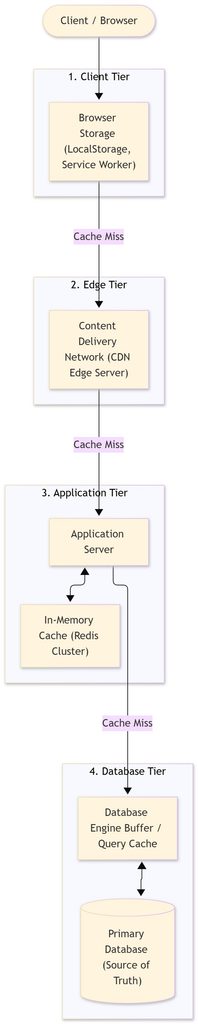
1. Client-Side Caching
The fastest request is the one that never leaves the user’s device. Modern browsers store static assets, scripts, stylesheets, and JSON payloads locally using HTTP cache headers, localStorage, IndexedDB, and Service Workers. Consequently, client-side caching delivers near-instant page reloads and enables offline experiences.
2. Edge / Content Delivery Network (CDN) Caching
For geographically dispersed users, network latency creates substantial delays. CDNs deploy points of presence (PoPs) globally to cache static files, images, videos, and static API payloads near end users. As a result, users in Tokyo and New York experience identical sub-second page loads without burdening your origin server.
3. Application-Tier In-Memory Caching
Application servers frequently query shared application-level caches, such as Redis or Memcached. This tier stores short-lived session states, user profiles, authentication tokens, and the output of resource-intensive calculations.
4. Database-Level Caching
Finally, database engines maintain their own internal buffer pools and query result caches. Techniques such as materialized views pre-aggregate complex joins and grouping operations, allowing databases to serve analytical queries without repeatedly parsing raw tables.
Data Synchronization Strategies Compared
Caching is not merely about choosing a storage medium; it requires choosing how data flows between the cache and your primary database (the source of truth). Different architectures prioritize either write latency, data durability, or absolute consistency.
       CACHE-ASIDE                      WRITE-THROUGH                     WRITE-BACK

    [App] ---> [Cache]               [App] ---> [Cache]               [App] ---> [Cache]
      |          |                                |                                |
(Miss)|          |(Hit)                           | (Synchronous)                  | (Async Queue)
      v          v                                v                                v
    [Database]                       [Database]                       [Database]
1. Cache-Aside (Lazy Loading)
Cache-aside represents the most common caching pattern across distributed systems.
- How it works: The application searches the cache first. If a cache hit occurs, the application immediately returns the data. Conversely, upon a cache miss, the application queries the database, stores the retrieved result in the cache, and then returns the response.
- Advantages: The cache stores only active data that clients actually query, preventing wasted memory. Furthermore, a cache crash does not take down the entire system.
- Trade-offs: Every cache miss incurs three network round-trips: reading from the cache, reading from the database, and writing back to the cache.
2. Write-Through Caching
Write-through prioritizes data consistency above all else.
- How it works: When updating data, the application writes directly to the cache. The cache synchronously updates the database before acknowledging the operation as successful.
- Advantages: The cache never serves stale data on reads, and reads remain exceptionally fast.
- Trade-offs: Every write incurs additional latency because two distinct storage systems must confirm the write operation before completion.
3. Write-Back (Write-Behind) Caching
High-volume write systems frequently deploy write-back caching to handle extreme write throughput.
- How it works: The application writes data straight into the cache and receives an immediate success response. Subsequently, the cache asynchronously flushes accumulated updates to the database in batches.
- Advantages: Write speeds increase dramatically because disk I/O bottlenecks disappear from the critical path.
- Trade-offs: If the cache server crashes before flushing dirty data to disk, you risk permanent data loss.
Do not use write-back caching for financial or auditable transactions unless you implement a persistent, distributed write-ahead log (WAL) alongside your in-memory tier.
4. Explicit / Refresh-Ahead Caching
In this model, backend developers program explicit background jobs to refresh cached records before their expiration timers elapse. While this approach grants granular control over data lifecycle and prevents read spikes, it introduces custom synchronization logic into the codebase.
Strategy Comparison Table
| Strategy | Primary Benefit | Latency Profile | Risk / Trade-Off | Ideal Workload |
|---|---|---|---|---|
| Cache-Aside | Memory efficiency | Low on hits, higher on misses | Potential stale reads | Read-heavy applications |
| Write-Through | Strict consistency | Higher write latency | Slower writes | Financial / inventory ledgers |
| Write-Back | Maximum write throughput | Ultra-fast writes | Data loss during crash | Telemetry, logging, gaming scores |
| Refresh-Ahead | Predictable read speed | Consistently low | Complex cache scheduling | High-traffic news / live scores |
Cache Eviction Policies: Managing Limited Memory
Because in-memory storage remains a finite and premium resource, caches eventually reach capacity. When memory exhausts, an eviction policy decides which keys to delete to make room for new records.
1. Least Recently Used (LRU)
LRU operates on the principle of temporal locality: data accessed recently will likely be accessed again soon. Therefore, the system evicts records that have sat untouched the longest. Because LRU mirrors typical web browsing patterns, it serves as the industry-standard default policy.
2. Least Frequently Used (LFU)
LFU evaluates long-term popularity by tracking how many times a key is requested. When space runs out, the system discards the items with the lowest access counts. As a result, LFU excels in systems featuring consistently popular reference data, such as trending hashtags or top-selling products.
3. First-In-First-Out (FIFO)
FIFO discards items strictly in the order they arrived, functioning like a queue. Although FIFO requires negligible CPU overhead to manage, it frequently evicts crucial hot data simply because that data was loaded early.
4. Time-to-Live (TTL)
TTL introduces a fixed expiration timestamp for each cached entry. Once the clock expires, the cache invalidates or purges the record automatically. Consequently, TTL suits time-sensitive information such as one-time passwords (OTPs), weather forecasts, and authentication sessions.
Production architectures routinely combine policies. For instance, Redis instances use TTL to guarantee data freshness while enforcing volatile-lru or allkeys-lru to prevent out-of-memory errors during traffic surges.
Redis in Action: The Standard for High-Performance Caching
Redis (Remote Dictionary Server) has emerged as the premier distributed caching engine. While relational databases prioritize complex query indexing and ACID durability, Redis keeps all datasets in RAM to deliver microsecond responses.
Beyond basic string key-value storage, Redis offers versatile data primitives and architectural capabilities:
- Built-in TTL Support: Automatically handles key expiration without requiring custom polling scripts.
- Pub/Sub Messaging: Facilitates event-driven notifications to invalidate caches across multiple application nodes simultaneously.
- Durability Options: Balances raw speed with point-in-time snapshots (RDB) and append-only files (AOF) so cached data survives process restarts.
- Specialized Data Structures: Native support for Hashes, Sorted Sets (for real-time leaderboards), Lists (for job queues), and HyperLogLogs.
Practical Implementation: Cache-Aside with Node.js and Redis
The following example demonstrates the cache-aside pattern using Redis and an async database stub:
import Redis from 'ioredis';
const redis = new Redis({ host: '127.0.0.1', port: 6379 });

// Simulated database fetch
async function fetchProductFromDatabase(productId) {
  console.log(`[DB] Querying database for product: ${productId}...`);
  return { id: productId, name: 'Ultra Wireless Headphones', price: 199.99 };
}

// Cache-Aside implementation
async function getProductDetails(productId) {
  const cacheKey = `product:${productId}`;
  const DEFAULT_TTL_SECONDS = 3600; // 1 hour

  // Step 1: Check cache
  const cachedData = await redis.get(cacheKey);
  if (cachedData) {
    console.log(`[CACHE HIT] Returning data from Redis for ${cacheKey}`);
    return JSON.parse(cachedData);
  }

  // Step 2: Handle Cache Miss
  console.log(`[CACHE MISS] Fetching fresh record from database...`);
  const product = await fetchProductFromDatabase(productId);

  if (product) {
    // Step 3: Populate cache with an expiration time (TTL)
    await redis.set(cacheKey, JSON.stringify(product), 'EX', DEFAULT_TTL_SECONDS);
  }

  return product;
}
Real-World Use Cases and Scenarios
To appreciate the tangible impact of caching, consider how modern architectures solve everyday operational bottlenecks:
1. E-Commerce Product Catalogs
During flash sales, millions of shoppers view the same catalog items every minute. Because product descriptions, specifications, and images change infrequently, engineers cache catalog payloads in Redis clusters with moderate TTLs (e.g., 15 minutes) and distribute images via CDNs. This stops millions of identical SQL queries from crashing the transactional database.
2. User Authentication and Session Stores
Web applications must validate user sessions on every single HTTP request. Rather than querying relational user tables millions of times per minute, developers store session tokens in Redis. The application validates session identity in sub-millisecond intervals and refreshes the TTL on each interaction.
3. Autocomplete and Search Suggestions
A fraction of search keywords generate the vast majority of search volume. By caching the results of popular queries and storing autocomplete prefix trees in memory, search engines bypass computationally heavy ranking pipelines for 80% of routine lookups.
4. Microservices Communication
When an order service repeatedly calls an exchange-rate service for currency conversions, network round-trips quickly compound. Placing an in-memory cache directly inside the caller service eliminates inter-service chatter, reduces operational costs, and insulates downstream services from cascading failure.
Overcoming Critical Caching Challenges
Aggressive caching brings immense speed, but unmanaged caches introduce insidious production failures:
                  CACHE STAMPEDE PREVENTION (MUTEX LOCK)
  Request 1 (Miss) ---> [Acquires Lock] ---> Queries DB ---> Updates Cache & Releases Lock
  Request 2 (Miss) ---> [Fails Lock]   ---> Waits or Serves Stale Data
  Request 3 (Miss) ---> [Fails Lock]   ---> Waits or Serves Stale Data
1. Cache Stampede (Thundering Herd)
- The Problem: When an extremely hot key expires, hundreds of concurrent requests experience a simultaneous cache miss. They all slam the database at the same instant, leading to sudden database CPU exhaustion and service outages.
- The Solution:
- Distributed Mutex Locks: Ensure only the first requesting process acquires a lock to query the database, while other requests wait briefly for the cache to refresh.
- Jittered TTLs: Append small, pseudo-random intervals to TTL values (e.g.,
3600 + rand(0, 300)seconds) so bulk entries expire at staggered times. - Stale-While-Revalidate: Allow background workers to update the cache ahead of expiration while clients temporarily consume slightly older data.
2. Stale Data and Cache Invalidation
- The Problem: The database updates, but the cache continues serving outdated values.
- The Solution: Invalidate keys immediately upon mutation via application hooks or event streams (using Change Data Capture with tools like Debezium or Kafka).
3. Distributed Cache Clustering
When your dataset surpasses the memory limit of a single machine, implement distributed caching tools:
- Redis Cluster: Employs master-replica nodes and consistent hash slots (16,384 slots) for seamless data partitioning and automatic failover.
- Memcached: Provides multi-threaded, bare-bones memory storage ideal for simple key-value reads.
- Hazelcast / Apache Ignite: Offer in-memory data grids that support distributed compute and transactions directly within enterprise clusters.
System Design Interview Cheat Sheet: Caching Q&A
Core Conceptual Questions
Q1: What is caching and why does it matter in system design?
Answer: Caching is the practice of storing frequently referenced data in an ultra-fast temporary storage layer (typically RAM) to minimize access latency. It decreases response times, shields slower persistent databases from traffic spikes, and allows systems to scale horizontally without multiplying hardware costs.
Q2: What are the primary caching layers in modern architectures?
Answer:
- Client-side: Browser caches and Service Workers store local UI assets and tokens.
- CDN / Edge: Edge servers cache static media files and localized API payloads.
- Application cache: In-memory key-value stores (Redis, Memcached) store session data and heavy query results.
- Database cache: Internal query caches and materialized views reduce redundant table scans.
Q3: Contrast Write-Through and Write-Back caching strategies.
Answer: Write-Through synchronously writes updates to both the cache and the database before confirming success. It guarantees consistency at the expense of write latency. Conversely, Write-Back writes solely to the cache first and commits updates to the database asynchronously. This accelerates write performance but risks data loss if the cache crashes prematurely.
Q4: How does Cache-Aside (Lazy Loading) operate?
Answer: Cache-Aside checks the cache on every read. On a cache hit, it returns the value immediately. On a cache miss, it fetches data from the database, populates the cache for future callers, and returns the response. It ensures that memory only stores requested keys.
Practical Implementation Questions
Q5: How do you structure a Redis cache within a microservices architecture?
Answer:
- Establish structured namespacing for keys (e.g.,
service:entity:idsuch asuserservice:user:4582). - Enforce deterministic JSON serialization or binary formats like Protobuf for bandwidth efficiency.
- Configure explicit connection pools and circuit breakers so database fallbacks engage smoothly if the Redis cluster drops offline.
Q6: How do you eliminate cache stampedes in production?
Answer:
- Wrap cache-miss database queries inside a distributed lock (e.g., Redis
SET NXor Redlock). - Implement the Stale-While-Revalidate HTTP pattern to return older data while updating in the background.
- Add randomized jitter to expiration timers to prevent synchronous key expirations.
Summary & Key Takeaways
Caching is not an afterthought to tack onto an application when performance falters. In resilient, high-volume systems, caching serves as a core architectural tier that protects databases, reduces latencies to microseconds, and facilitates sustainable traffic growth.
When designing your caching layer, remember these foundational principles:
- Identify repeated, expensive work: Move hot data as close to the consumer as possible.
- Match strategies to workloads: Leverage Cache-Aside for read-intensive workloads, Write-Through for strict consistency, and Write-Back for extreme write throughput.
- Control memory consumption: Pair intelligent eviction algorithms (like LRU) with explicit TTLs.
- Guard against stampedes: Deploy distributed locks and staggered expiration times to keep your backend systems safe under heavy traffic.